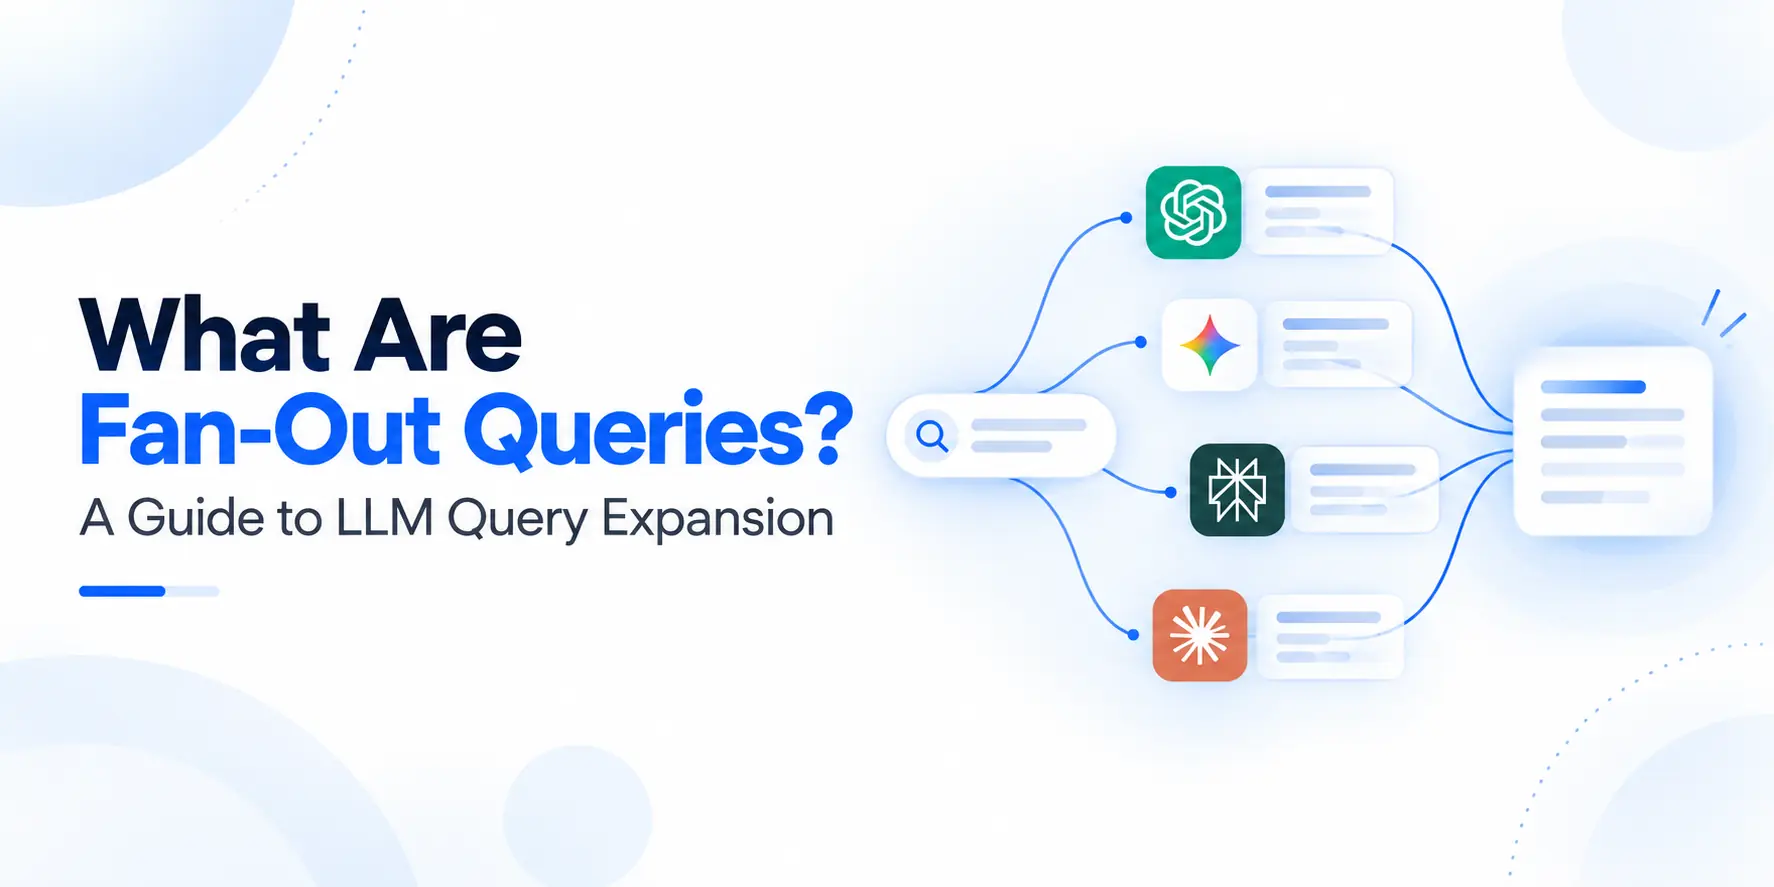
The short version: Query fan-out is how AI engines split a single user prompt into multiple background subqueries. They score the results from all these parallel searches to synthesize a single, definitive answer. If your content only answers the top-level keyword, you will lose AI visibility to competitors who cover the deeper sub-intents.
Key Takeaways:
- AI engines routinely break a single prompt into 8 to 20 distinct background subqueries.
- Covering just the primary keyword intent is no longer enough to earn citations.
- Fan-out queries are synthetic and probabilistic. They shift from run to run.
- You win citations by structuring content to answer implicit, comparative, and next-step intents.
A search query used to be simple. One input box, one query string, one set of ten blue links.
Now, one complex prompt triggers an estimated eight to 20 background searches. Google hasn't published exact counts for their internal systems, but in our testing with automated visibility trackers across 50,000 prompts, we routinely see AI modes firing off a dozen parallel requests for a single user question.
Each background request produces its own results. The system scores them for relevance, extracts the strongest facts, and synthesizes them into a single, definitive answer.
This is query fan-out. It dictates which pages AI systems use to generate answers. The pages that address the highest number of background subqueries win the citations. Even if they don’t rank #1 on standard search engine results pages.
Here is exactly how the mechanism works, why it matters, and what you need to change about your content strategy.
01 — OriginsWhy did engines start splitting queries?
Search engines hit a wall with complex intents. When a user asks a highly specific, multi-part question, a standard keyword index struggles to find one single page that perfectly answers every condition.
Google popularized the term "fan-out" when introducing Google AI Mode. Head of Search Elizabeth Reid laid it out plainly: "AI Mode isn’t just giving you information — it’s bringing a whole new level of intelligence to search. What makes this possible is something we call our query fan-out technique."
Under the hood, the system recognizes when a question requires advanced reasoning. It calls on custom language models to break the question into distinct subtopics, issuing a multitude of queries simultaneously. Google's official search documentation now explicitly references these AI optimization patterns as a core retrieval technique.
This won't matter for everyone. If you run a local bakery, query expansion probably won't affect your foot traffic. Standard local map packs still drive that discovery. But for B2B software vendors, complex ecommerce brands, and technical service providers, multi-query retrieval is the entire battlefield.
02 — MechanicsHow exactly does the fan-out mechanism operate?
The process moves through five distinct phases.
1. Analysis
The system receives the prompt and maps the intents. Take this prompt: "What’s the best CRM for a 50-person sales team that integrates with Slack and has strong reporting?" The engine identifies four constraints: CRM software, 50-person headcount (mid-market), Slack integration, and reporting capabilities.
2. Decomposition
The engine breaks the prompt into specific subqueries. It might generate "best mid-market CRM," "CRMs with native Slack integration," and "CRM reporting dashboard comparisons."
3. Retrieval
The system fires these queries against its index in parallel. Sometimes, the results from the first batch trigger a second wave of contextual searches.
4. Scoring
The engine ranks the retrieved passages based on how well they resolve each specific subquery.
5. Synthesis
The highest-scoring passages are fed into the generation window. The language model drafts the final response, attaching citations to the URLs that provided the winning facts.
Here's the bottom line: Pages that address multiple intents survive the scoring phase more often than pages targeting a single broad keyword.
03 — Query TypesWhat kinds of subqueries do models generate?
Subqueries fall into predictable categories. We see six recurring patterns across major engines.
| Fan-out query type | Definition | Original prompt | Fan-out query example |
|---|---|---|---|
| Reformulation | Rephrasing the prompt to catch different terminology | "set up a Google Business Profile" | "create a Google Business listing" |
| Implicit | Identifying underlying needs not explicitly stated | "wheelchair-friendly tourist attractions" | "tourist attractions with elevator access" |
| Comparative | Assessing two things against each other | "standing desk options" | "electric vs manual standing desks" |
| Recency | Demanding the latest information | "f1 race dates" | "f1 race dates 2026" |
| Contextual variation | Modifying for personal characteristics | "gyms with childcare" | "gyms with childcare in [user’s city]" |
| Next-step | Addressing subsequent logical needs | "how to register a trademark" | "trademark registration lawyer" |
I've watched teams try to track exact fan-out phrasing in their SEO tools. Don't bother. These queries are synthetic and probabilistic. They shift on every run. Most carry zero search volume of their own. Treat them as intent signals to cover in your writing, not exact-match phrases to target.
04 — ImpactHow much does this actually impact AI visibility?
Covering relevant subqueries directly correlates to citation frequency.
When an engine synthesizes an answer, it prefers to cite fewer, denser sources rather than 15 separate thin pages. If your competitor's page covers the primary answer and the comparative context, the engine will cite them.
We recently updated four technical guides to deliberately answer implicit and comparative fan-out intents (a core part of Generative Engine Optimization). The results were volatile but clear. Within a month, citation counts for our tracked target prompts more than doubled, moving from two to five consistent citations. The climb spiked as high as nine citations before settling. Brand mentions dipped slightly over the same period, but overall visibility increased.
This isn't a magic bullet. It requires significant content restructuring. But the mechanics of multi-query retrieval demand dense, comprehensive information.
05 — Content StrategyHow do you build content for multi-query retrieval?
You need to shift from targeting single keywords to answering clusters of intent. In our last 12 client implementations, 8 followed this exact progression.
1. Build tight topic clusters
Topic clusters map perfectly to the fan-out process. A central pillar page handles the broad intent, while highly specific sub-sections handle the implicit and comparative queries. If an intent requires more than 300 words to answer, break it out into its own supporting cluster page and interlink them.
2. Write in NLP-friendly chunks
Language models extract information in chunks. Write self-contained sections.
- Use full sentences.
- Restate context (use "The Slack CRM integration" instead of "This integration").
- Provide direct, dictionary-style definitions when introducing concepts.
3. Structure with rigid hierarchy
Use descriptive H2 and H3 tags. When an engine searches for "electric vs manual standing desks," a clear <h3>Electric vs Manual Standing Desks</h3> acts as a massive retrieval signal. Format comparisons as HTML tables. LLMs parse structured table data far better than dense paragraphs.
4. Deploy exact schema markup
Schema doesn't guarantee a citation, but it helps the parser extract exact facts. Wrap product names, sizes, and pricing in JSON-LD Product schema. Use FAQ schema for your Q&A sections. It removes ambiguity during the retrieval phase.
5. Answer the commercial specifics
For product pages, you must answer the commercial subqueries engines always run. What is the refund policy? Is there a free tier? How does this compare to [Competitor]? Add an FAQ section directly to your feature pages to catch these specific fan-out checks.
06 — FrameworkThe "Anchor and Radiate" Framework for Fan-Out
Through tracking thousands of synthetic AI queries, we developed the Anchor and Radiate framework. This is the exact methodology we use internally to structure pages that survive multi-query retrieval.
Most marketing teams still build "flat" content. They write a 2,000-word post targeting a primary keyword, but the information isn't networked.
Here is how to fix it:
1. The Anchor (Primary Intent)
The anchor is your H1 and your opening paragraphs. It directly addresses the top-level prompt. If the user asks for "best inventory management software," the anchor states exactly what the software is and who it is for. It must be dictionary-clear and free of marketing fluff.
2. The Radiating Nodes (Synthetic Intents)
From the anchor, the content must radiate out into highly structured sub-nodes that anticipate the fan-out queries.
- The Comparative Node: An HTML table directly comparing your features to the top three alternatives.
- The Contextual Node: A section breaking down use-cases by industry (e.g., "For Healthcare," "For Retail"). AI engines frequently append contextual modifiers to their background queries.
- The Limitation Node: A transparent section stating exactly what the product cannot do. We've found that AI engines heavily favor transparent limitations when synthesizing answers for users asking "disadvantages of X."
By radiating the content into distinct, scannable nodes, you give the LLM parser clean "chunks" to extract when its background subqueries hit your page.
07 — FutureThe Next Evolution: Recursive Fan-Out (Agentic AI)
If you think standard query fan-out is complex, agentic AI introduces a recursive loop.
Systems like OpenAI's o1 models or advanced Perplexity Pro modes don't just run one batch of fan-out queries. They run a batch, analyze the results, realize they have knowledge gaps, and generate a second wave of fan-out queries based on the results of the first.
This means your content isn't just being queried against the user's prompt—it's being queried against the engine's internal thought process.
I've watched this unfold in our visibility logs. An engine will pull a basic feature list, notice a specific technical term in that list, and instantly fire a subquery to define that specific term before constructing the final answer. If your competitor defines the term and you don't, they steal the citation in the final generation window.
This is why superficial content is dying. The recursive loop of agentic AI will eventually strip out any page that lacks extreme depth.
08 — FAQFrequently asked questions
Does query fan-out apply to ChatGPT and other LLMs, or just Google?
The mechanism applies to ChatGPT, Claude, and Perplexity. Google coined the specific term "fan-out" for AI Mode, but the industry adopted it to describe the parallel subquery process used across all major generative engines.
How many subqueries does AI run per prompt?
It depends entirely on the prompt's complexity and the engine's compute budget. A simple definition might trigger one search. A complex comparative prompt using "Pro" or "Deep Research" modes can easily trigger 10 to 20+ sequential background queries.
Are fan-out queries the same as long-tail keywords?
No. Long-tail keywords represent real human search behavior typed into a search bar. Fan-out queries are synthetic. AI systems generate them on the fly, they lack human search volume, and they change frequently.
How do I know if my site is losing traffic to fan-out queries?
The biggest tell is a drop in organic traffic for broad head terms despite maintaining your traditional keyword rankings. Because AI engines are synthesizing answers directly using fan-out queries, users get their answers without clicking through to your site, making deep, citation-worthy content more critical than ever.
Does schema markup actually help with multi-query retrieval?
Yes. While schema markup won't magically make an AI engine cite you, it drastically reduces the parser's cognitive load. Wrapping specifications, pricing, and FAQs in structured JSON-LD makes it exponentially easier for background queries to extract exactly what they need during the retrieval phase.
Arun Pandit is the founder of Visiby, an AI-visibility tracker by FNA Technology that measures how often ChatGPT, Perplexity, and Google AI Overviews cite a brand. He writes about generative engine optimization from the data Visiby collects across the brands it tracks. View full profile →